Text-to-speech API with character-level timestamps
Get start and end times for every spoken character, streamed alongside the audio. Derive word-level timestamps for live text highlighting, captions, read-along experiences, and voice-agent interruptions.
$0.70 per generated hour.
Trusted by teams building global voice products















TTS timestamps streamed with the audio
Soniox Text-to-Speech API returns character-level timing data while speech is being generated. Keep text and audio synchronized in real time without running a separate alignment step after synthesis.
Highlight words as they are spoken
Use character timestamps directly for character-by-character highlighting, or group them into words for karaoke-style captions, transcripts, reading interfaces, and other synchronized text experiences.

Natural and expressive
I thought I knew exactly how the evening would unfold. Then the phone rang. For a moment, I considered letting it go to voicemail—but something told me to answer.

Conversational
Absolutely. I found three flights that arrive before noon. The first is the least expensive, but the second gives you a much shorter connection. Would you like me to compare them?

Storytelling
By the time we reached the top of the hill, the sun was already beginning to set. We stopped for a moment, looked back at the road behind us, and realized the entire valley had turned gold.
Know exactly what a voice agent finished saying
When a user interrupts an agent mid-response, character timestamps show how far playback reached. Use the spoken-so-far text to keep your LLM or dialogue system aligned with what the user actually heard.
Synchronize every script and language
Character-level alignment works naturally for multilingual text, language mixing, and writing systems where word boundaries are not always represented by spaces.
Your order is ready for pickup. 店頭で注文番号 A-7392 をお見せください.
To enable the new feature, open Settings and select 음성 복제, then tap Continue.
Your appointment is confirmed for Monday at 11 a.m. कृपया दस मिनट पहले पहुँचें.
The deployment completed successfully. Bitte prüfen Sie jetzt die Produktionsumgebung und bestätigen Sie, dass alles funktioniert.
Your meeting with Nguyễn Minh Anh is scheduled for 3 p.m. at our office near Place de la République in Paris.

Need word-level TTS timestamps? Start with character timing
Soniox returns the start and end time of every spoken character. That gives you the information needed to create word-level timestamps while preserving finer-grained timing whenever your application needs it.
Group character timestamps into words
Concatenate the character arrays from each audio frame, then group characters between whitespace. A word begins at the start of its first character and ends at the end of its last.
function toWords(characters, starts, ends) {
  const words = [];
  let word = null;

  characters.forEach((char, i) => {
    if (/\s/.test(char)) {
      word = null;
      return;
    }

    if (!word) {
      word = {
        text: '',
        start: starts[i],
        end: ends[i],
      };
      words.push(word);
    }

    word.text += char;
    word.end = ends[i];
  });

  return words;
}
Word-level timestamp output
The character timing can be reduced to the word timing most caption, transcript, and read-along interfaces need.
[
  {
    "text": "Hello",
    "start": 0.0,
    "end": 0.5
  }
]
Why Soniox returns character-level timestamps
Character timing preserves more information. You can derive word-level timing from it, highlight individual characters, handle scripts without whitespace boundaries, or determine where playback stopped inside a word.
Turn on character timestamps with one field
Set return_timestamps to true when you start a Soniox Text-to-Speech WebSocket stream. Audio responses can then include character-to-audio alignment data alongside the generated audio.
Request timestamps
{
  "api_key": "<SONIOX_API_KEY>",
  "model": "tts-rt-v2",
  "language": "en",
  "voice": "Adrian",
  "audio_format": "pcm_s16le",
  "sample_rate": 24000,
  "stream_id": "stream-001",
  "return_timestamps": true
}
Receive audio and alignment
{
  "stream_id": "stream-001",
  "audio": "<base64-encoded-audio-chunk>",
  "timestamps": {
    "characters": ["H", "e", "l", "l", "o"],
    "character_start_times_seconds": [0.0, 0.1, 0.2, 0.3, 0.4],
    "character_end_times_seconds": [0.1, 0.2, 0.3, 0.4, 0.5]
  }
}Real-time text-to-audio alignment
Timestamps are designed for streaming applications. Alignment data arrives incrementally with generated speech, so your interface can react while the audio is still playing.
Streamed with the audio
Character timestamps arrive incrementally alongside generated audio, so your application can synchronize text while speech is still playing.
Aligned to spoken output
Each timestamp maps generated speech back to the normalized text Soniox actually speaks, giving your application precise text-to-audio alignment.
One continuous timeline
Times are non-decreasing across the stream and remain aligned as audio arrives across multiple chunks.
One timing entry per character
Receive a start and end time for every spoken character, giving you finer-grained alignment than word-level timing alone.
Word highlighting and captions in real time
Because timestamp data is returned during synthesis, applications can update captions, transcripts, and read-along interfaces progressively instead of waiting for the complete generated clip.
Start highlighting while speech is still generating
Send text progressively, begin playback before the complete response is available, and receive timing data alongside the generated audio.
TTS timing for more than captions
Character-level speech timing gives applications a precise connection between generated text and generated audio.
Live text highlighting
Follow generated speech word by word or character by character in captions, transcripts, karaoke-style interfaces, and read-along experiences.
Interruption tracking
Determine exactly how much of a generated response was actually spoken before playback stopped or a user interrupted.
Text-audio synchronization
Keep text interfaces, subtitles, learning content, and other application state synchronized with generated speech.
Estimate your text-to-speech cost
Set your expected generated speech volume to estimate the cost of using Soniox Text-to-Speech API with character-level timing.
Pricing calculator
Stop overpaying for speech AI
1,000 hours of speech / month
Pricing assumptions
Based on public pay-as-you-go pricing. Enterprise discounts and committed-use contracts may differ. Some providers charge separately for certain features. The calculator uses the public price for the provider configuration that most closely matches Soniox.
Speech infrastructure for massive scale
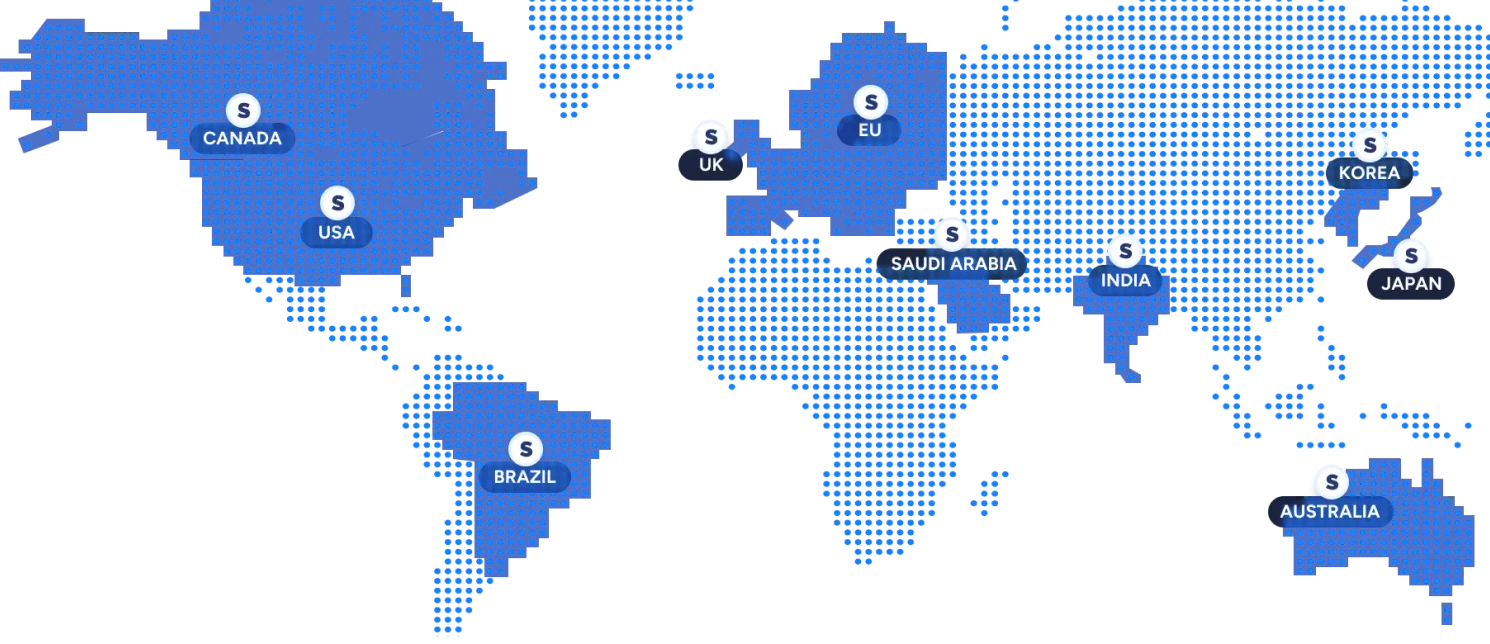
Build on one API and deploy in your region
Use the same models and API everywhere, with in-region processing to meet latency, data residency, and regulatory requirements.
Available: US, EU, Japan, India
Coming soon: Korea, Australia, Canada, Saudi Arabia, UK, Brazil
Run mission-critical systems with confidence
- 99.9% uptime
Production-hardened infrastructure with monitoring and redundancy. - low-latency streaming
Process speech in real time with low latency for responsive voice applications. - Priority support
Severity-based incident response with direct access to the Soniox team.
"Before Soniox, our international users always had a noticeably different experience. Now accuracy and responsiveness match across all regions…it feels like one system instead of five."
Alon Yair CTO of Onvego
Build speech experiences where text and audio stay in sync
Use character-level and derived word-level timing for voice-agent interruptions, captions, read-along interfaces, learning products, narrated content, and interactive applications.
Voice agents
Track exactly what an agent finished saying before a user interrupts, so conversation state stays aligned with what the user actually heard.
Read-along and accessibility
Highlight text word by word or character by character as generated speech plays in reading assistants and accessible interfaces.
E-learning and language apps
Synchronize spoken lessons with vocabulary, subtitles, transcripts, and interactive read-along experiences.
Captions and video
Align generated narration with captions, subtitles, transcript displays, and other time-based video interfaces.
Audiobooks and narration
Build synchronized reading experiences where text follows long-form narration word by word as the audio plays.
Games and interactive characters
Keep dialogue text synchronized with generated character speech and preserve accurate state when runtime dialogue is interrupted.
Privacy and compliance, built right in
Never stored, never saved.
Audio stays in memory, everything is processed in real-time.
Built for privacy-critical use cases.
Adhering to leading global security, privacy, and compliance standards.
Trusted where privacy matters most.
Used in industries where speech is sensitive, from healthcare to enterprise.
Frequently asked questions about TTS timestamps
Does Soniox Text-to-Speech return character-level timestamps?
Does Soniox Text-to-Speech provide word-level timestamps?
Soniox natively returns character-level timestamps rather than a separate word-level array.
Word-level timestamps are straightforward to derive: group the characters belonging to each word, use the first character's start time as the word start, and the last character's end time as the word end.
What are character-level TTS timestamps?
What are word-level timestamps in text-to-speech?
Are TTS timestamps the same as speech marks?
Can I use Soniox timestamps for word-by-word text highlighting?
Can I use timestamps for character-by-character highlighting?
Do Soniox TTS timestamps stream in real time?
How do I enable timestamps in Soniox Text-to-Speech API?
return_timestamps: true in the configuration message when starting a Text-to-Speech WebSocket stream. Timestamp output is disabled by default.Are TTS timestamps available through the REST API?
How do timestamps help with voice-agent interruptions?
Can I use timestamps for text-to-audio alignment?
Do timestamps work with multilingual and mixed-language TTS?
Why can the timestamp text differ from my original input?
How much does Soniox Text-to-Speech cost?
How do I start building with TTS timestamps?
Start a Soniox Text-to-Speech WebSocket stream with return_timestamps: true and process the character, start-time, and end-time arrays returned with generated audio.
Read the TTS timestamps documentation for the complete request and response format.
Keep every word in sync with the voice
Get character-level timestamps directly from Soniox Text-to-Speech API and derive the word-level timing your product needs for highlighting, captions, read-along experiences, and real-time voice interactions.
Ready to get started?
Create an account instantly, or contact us to design a custom package for your business.
Build with APIDocumentation
Get up and running in minutes and spend your time building, not wrestling with the API.
Explore docsSee what you’ll pay
Pay only for what you use with our flexible pricing. Built to scale with you.
Pricing details