Text-to-speech API for audiobook and narration products
Build audiobook platforms, reading apps, publishing workflows, and long-form narration products with Soniox Text-to-Speech API. Choose from 200+ studio-quality voices or clone your own, direct dialogue and emotion with audio tags, and generate narration across 60+ languages.
$0.70 per generated hour.
Trusted by teams building global voice products















Narration built for long-form products
Long-form listening exposes flat delivery, mispronounced names, inconsistent voices, and unnatural pacing quickly. Soniox Text-to-Speech API gives publishing and reading products expressive narration with a stable voice identity from the first paragraph to the final chapter.
Natural storytelling at scale
Generate narration with natural rhythm, pacing, emphasis, and expression that adapts to the meaning of the text, so your product can produce long-form audio that sounds like storytelling rather than text being read aloud.

Narrative
I thought I knew exactly how the evening would unfold. Then the phone rang. For a moment, I considered letting it go to voicemail—but something told me to answer.

Descriptive
By the time we reached the top of the hill, the sun was already beginning to set. We stopped for a moment, looked back at the road behind us, and realized the entire valley had turned gold.
Add expressive dialogue and emotion
Use audio tags to direct whispers, laughter, hesitation, tension, sadness, and other vocal delivery line by line. Build expressive fiction and dramatic narration without manually editing every generated clip.
Handle names and places correctly
Books and long-form content often contain names from many languages. Soniox uses language and context to pronounce people, places, and borrowed words naturally inside the surrounding sentence.
Your appointment with Siobhan O’Connor is confirmed.
Nguyễn Minh Anh will be joining the meeting shortly.
Our Asian engineering office is located in Guangzhou.
Your hotel is located near the historic center of Aix-en-Provence.

Support technical and specialist content
Build narration for medicine, science, law, finance, engineering, and other specialist domains with accurate pronunciation of terminology, names, numbers, and technical language.
Clone narrator and author voices
Create a voice from a short recording of an author, narrator, presenter, or approved brand voice, then use that identity consistently across books, series, and translated editions.
Localize narration across 60+ languages
Every built-in and cloned Soniox voice speaks all 60+ supported languages. Build multilingual editions without maintaining a separate narrator or voice pipeline for every market.
From manuscript to generated audiobook
Build an automated narration pipeline that turns manuscript text into structured chapter audio for publishing, reading, and content products.
Split
Split chapters into passages at paragraph or sentence boundaries. Each request generates up to 2 minutes of audio.
Direct
Add audio tags to dialogue and key passages where your product needs a specific emotion, pace, volume, pitch, or delivery.
Generate
Send passages to Soniox Text-to-Speech API with the same built-in or cloned voice, and run up to 5 streams on one WebSocket connection.
Assemble
Join generated passages into chapter files in the format your product or distributor expects, and preserve timestamps for synchronized reading experiences.
Narration API features for production pipelines
Build long-form narration with programmatic control over performance, narrator identity, audio output, synchronization, and multilingual generation.
Expressive audio tags
Direct emotion, volume, pace, and pitch inline with tags like [whispering], [sad], or [slowly]. Tags are written in English for every text language.
Voice cloning
Create an author or narrator voice from a reference clip in Soniox Console or through the API, then use its voice ID like any built-in voice across every supported language.
Explore voice cloningPublishing audio formats
Generate WAV, FLAC, MP3, AAC, Opus, or raw PCM at sample rates up to 48 kHz, with MP3 and AAC bitrates up to 320 kbps.
Explore audio formatsCharacter-level timestamps
Receive start and end times for every spoken character so reading apps can synchronize text highlighting, navigation, captions, and other interface elements with narration.
Explore timestampsSpeech infrastructure for massive scale
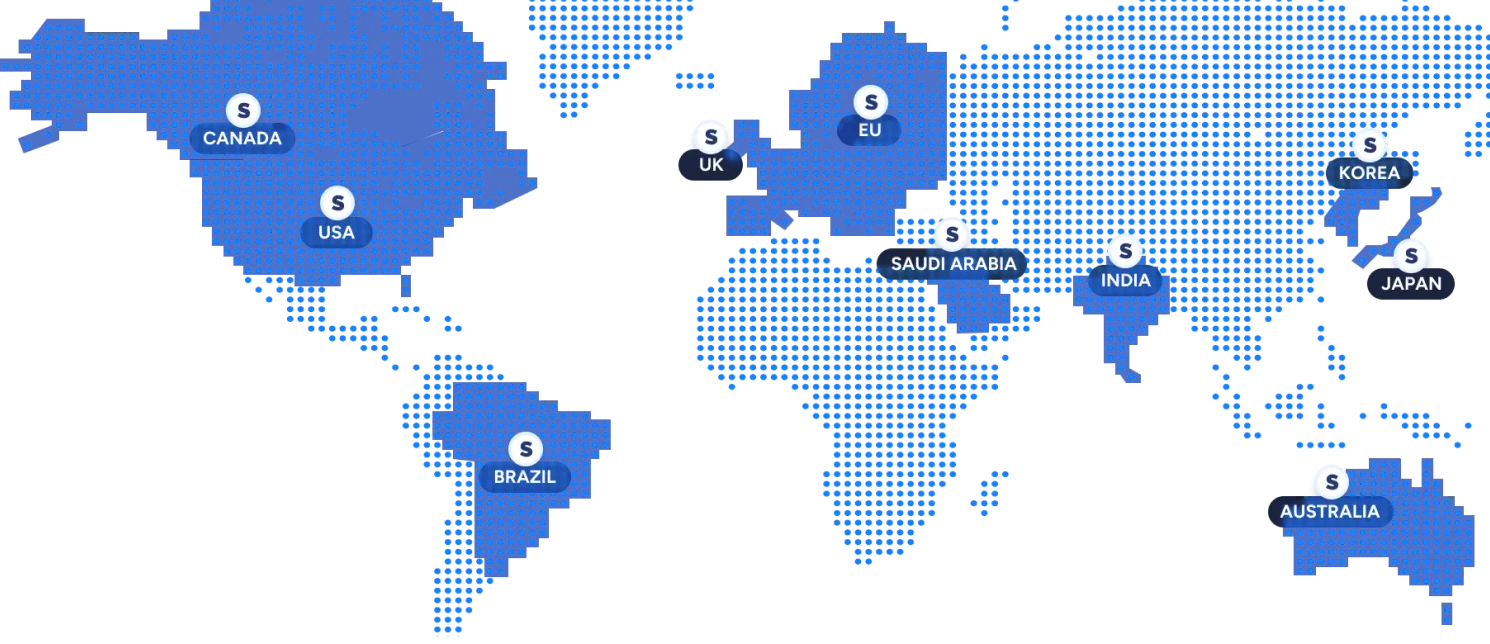
Build on one API and deploy in your region
Use the same models and API everywhere, with in-region processing to meet latency, data residency, and regulatory requirements.
Available: US, EU, Japan, India
Coming soon: Korea, Australia, Canada, Saudi Arabia, UK, Brazil
Run mission-critical systems with confidence
- 99.9% uptime
Production-hardened infrastructure with monitoring and redundancy. - low-latency streaming
Process speech in real time with low latency for responsive voice applications. - Priority support
Severity-based incident response with direct access to the Soniox team.
"Before Soniox, our international users always had a noticeably different experience. Now accuracy and responsiveness match across all regions…it feels like one system instead of five."
Alon Yair CTO of Onvego
Build narration into every reading product
Add long-form AI narration to publishing platforms, author tools, e-readers, content products, learning apps, and automated audio workflows.
Audiobook platforms
Build automated audiobook generation into publishing platforms, author tools, and content workflows with consistent built-in or cloned narrator voices.
Author voice products
Let publishers and author platforms clone an approved author voice and generate narrated editions programmatically across languages.
Multilingual publishing
Add translated audio editions to publishing workflows while preserving the same narrator voice across 60+ languages.
Read-along and e-reader apps
Use character-level timestamps to highlight text as it is spoken in reading apps, language-learning products, and accessible reading experiences.
Content and publishing platforms
Add listen versions of articles, newsletters, reports, documentation, and other long-form content directly inside your product.
Education and learning products
Build narration into textbooks, courseware, and learning platforms with accurate pronunciation of domain terms, names, and numbers.
Privacy and compliance, built right in
Never stored, never saved.
Audio stays in memory, everything is processed in real-time.
Built for privacy-critical use cases.
Adhering to leading global security, privacy, and compliance standards.
Trusted where privacy matters most.
Used in industries where speech is sensitive, from healthcare to enterprise.
Frequently asked questions about audiobook narration APIs
Can I build an audiobook product with a text-to-speech API?
Yes. Soniox Text-to-Speech API turns manuscript text into generated narration using built-in or cloned voices.
Your application can split books into passages, generate audio programmatically, assemble chapter files, and add narration to publishing, reading, or audiobook workflows.
How do I generate narration for a full-length book?
Each REST request or WebSocket stream generates up to 2 minutes of audio. Split chapters into passages at paragraph or sentence boundaries and send each passage as its own request or stream.
Use the same voice ID across every passage, then combine the generated audio in sequence to build complete chapters.
Which voices can I offer for audiobook narration?
Soniox provides 200+ built-in studio-quality voices tagged by gender, age, accent, use case, and style.
You can also create cloned narrator or author voices. Every built-in and cloned voice works across all 60+ supported languages.
Can my product generate narration in an author's cloned voice?
Yes. Upload a clean reference clip of up to 20 seconds of audio through Soniox Console or the API. Soniox returns a voice ID that your application can use like a built-in voice.
The cloned voice can generate the original book and translated editions across all 60+ supported languages.
Can I control dialogue, emotion, and narration style?
Yes. Add audio tags directly to the text. Tags can control emotion, volume, pace, pitch, and voice quality, for example [whispering], [trembling voice], or [slowly].
Tags are written in English even when the generated narration is in another language.
How does Soniox handle character names, places, and foreign words?
Can I build multilingual audiobook and publishing products?
Yes. Soniox Text-to-Speech supports 60+ languages, and the same built-in or cloned voice can be used across every supported language.
This lets your product generate translated audio editions while preserving the same narrator identity across markets.
Which audio formats can my product generate?
Can I build synchronized read-along highlighting?
How much does generated audiobook narration cost?
Build long-form narration into your product
Add expressive audiobook narration, cloned voices, multilingual generation, production-ready audio, and synchronized timestamps to the publishing and reading products you build with Soniox Text-to-Speech API.