Speech-to-text API built for smart glasses and wearables
Stream speech from glasses, earbuds, watches, pins, and other wearable devices into accurate real-time transcription and translation. Build live captions, hands-free voice input, accessibility, and wearable AI experiences across 60+ languages.
Trusted by teams building global voice products















Wearable speech has to keep up with the real world
Wearables capture speech wherever users are: in conversations, on the move, at work, while traveling, or whenever reaching for a phone would interrupt the moment. Transcription has to arrive quickly, understand natural speech, and work across the languages and vocabulary people actually use.
Stream words as they are spoken
Receive transcription continuously as audio arrives so captions, voice interfaces, and other experiences can update in real time.
Understand real conversations
Recognize natural speech, names, numbers, places, and conversational vocabulary instead of limiting users to rigid commands.
Work across 60+ languages
Build multilingual wearable experiences with one speech model, automatic language identification, and real-time translation.
Keep live audio transient
Real-time API audio is processed transiently and not stored by Soniox, making it suitable for privacy-sensitive wearable experiences.
{ "region": "" }
From microphone to wearable experience
Connect the microphone in your device or companion app to Soniox and turn live speech into text your wearable can display, store, or act on.
Capture
Capture microphone audio from glasses, earbuds, watches, pins, or a connected companion device.
Stream
Send live audio over WebSocket and receive transcription tokens continuously as speech is processed.
Understand
Detect speech, speakers, languages, and important vocabulary with structured real-time output.
Use it
Render captions, show translations, save notes, trigger actions, or send speech into your AI stack.
Speech capabilities built for wearable experiences
Wearable products put speech recognition directly into the user experience. Soniox gives you the real-time speech primitives to make that experience fast, multilingual, and useful.
Real-time streaming transcription
Stream live audio and receive provisional and finalized transcription tokens as speech happens, without waiting for a complete recording.
Explore real-time transcriptionLive speech translation
Stream the original transcript and translated text together so smart glasses and other wearables can display translations while the conversation is still happening.
Explore real-time translationSpeaker-aware conversations
Identify speaker changes in conversations so captions, notes, and memory experiences can preserve who said what.
Explore speaker diarizationContext-aware recognition
Provide names, places, product terminology, topics, and other relevant context so your wearable recognizes the words that matter to your users.
Explore context customizationOne speech model for a multilingual world
Wearables travel with their users. They move between countries, workplaces, homes, and conversations where language can change at any moment. Soniox handles 60+ languages with one unified speech model.
Automatic language identification
Detect spoken languages automatically, including conversations where users switch languages without changing a setting or restarting transcription.
Explore language identificationTranslation while people are speaking
Turn live speech into translated text across supported languages so users can read conversations directly on glasses, watches, or companion displays.
Explore speech translationSpeech infrastructure for massive scale
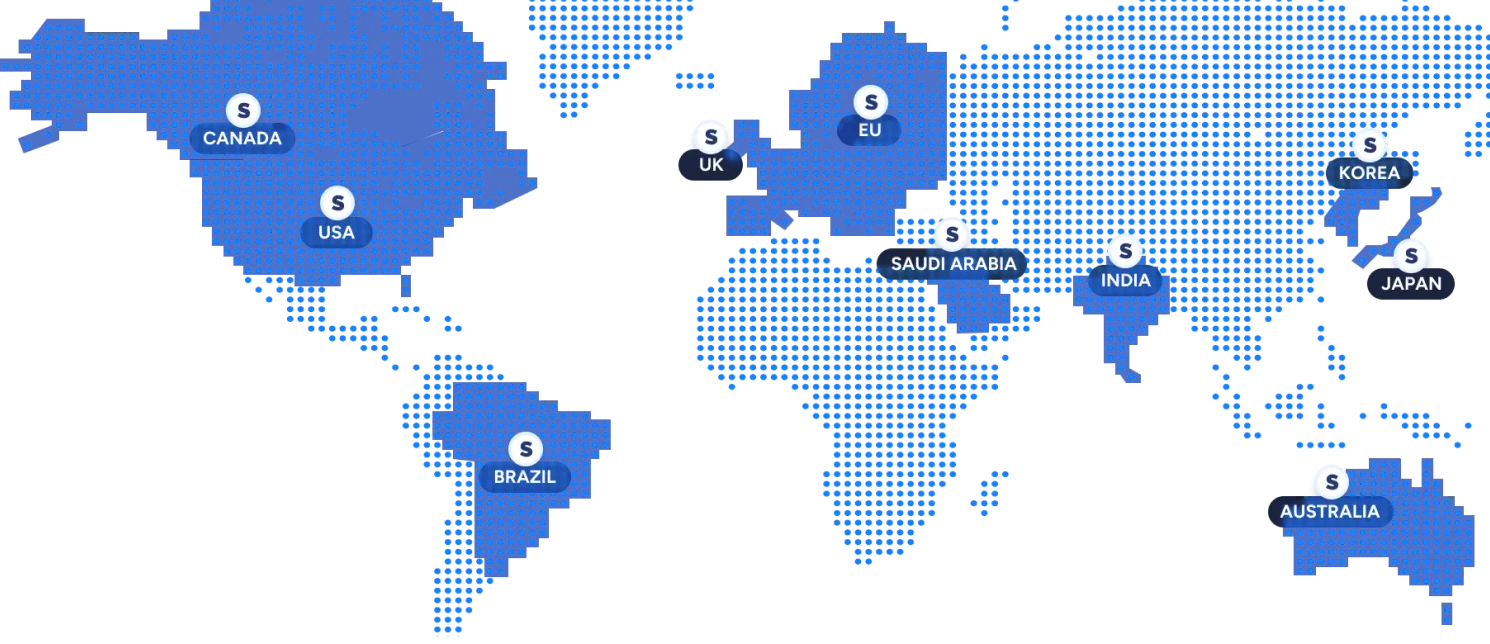
Build on one API and deploy in your region
Use the same models and API everywhere, with in-region processing to meet latency, data residency, and regulatory requirements.
Available: US, EU, Japan, India
Coming soon: Korea, Australia, Canada, Saudi Arabia, UK, Brazil
Run mission-critical systems with confidence
- 99.9% uptime
Production-hardened infrastructure with monitoring and redundancy. - low-latency streaming
Process speech in real time with low latency for responsive voice applications. - Priority support
Severity-based incident response with direct access to the Soniox team.
"Before Soniox, our international users always had a noticeably different experience. Now accuracy and responsiveness match across all regions…it feels like one system instead of five."
Alon Yair CTO of Onvego
Built for every kind of voice-enabled wearable
Build speech into devices users can wear all day, from live-caption glasses and translation earbuds to watches, AI pins, and hands-free assistants.
Smart glasses and displays
Stream live captions, translations, and conversational context directly into heads-up displays and smart glasses.
Accessibility wearables
Turn nearby speech into real-time captions that help users follow conversations without looking down at a phone.
Earbuds and hearables
Add live transcription, translation, and voice input to audio wearables built for communication and hands-free interaction.
Smartwatches
Capture voice notes, dictation, messages, and spoken commands from compact devices where voice is the natural input.
AI pins and pendants
Turn conversations and spontaneous speech into structured text for memory, notes, search, and personal AI experiences.
Wearable AI assistants
Give wearable assistants continuous access to accurate speech input for questions, commands, context, and downstream AI.
Privacy and compliance, built right in
Never stored, never saved.
Audio stays in memory, everything is processed in real-time.
Built for privacy-critical use cases.
Adhering to leading global security, privacy, and compliance standards.
Trusted where privacy matters most.
Used in industries where speech is sensitive, from healthcare to enterprise.
Frequently asked questions about Soniox for wearables
Is Soniox suitable for speech-to-text on smart glasses and wearable devices?
Yes. Soniox provides a real-time Speech-to-Text API for streaming live microphone audio and receiving transcription as speech is processed.
It can be used to build smart-glasses captions, translation, voice input, accessibility features, wearable assistants, voice notes, and other speech-enabled wearable experiences.
Can I build real-time captions for smart glasses?
Yes. Soniox returns transcription tokens continuously over its real-time WebSocket API, allowing your application to update captions while a person is still speaking.
Your wearable or companion application controls how those tokens are rendered in the device interface.
Can Soniox translate conversations in real time on a wearable?
Yes. Real-time speech-to-text translation returns the original transcript and translated text as a streaming token sequence.
This is well suited to smart glasses and other wearable displays where translated captions need to appear while the conversation is happening.
Does Soniox run directly on the wearable?
Soniox Speech-to-Text is a cloud API rather than an on-device speech recognition model.
Your wearable or companion application captures audio and streams it to Soniox over a real-time WebSocket connection, then uses the returned transcript or translation in the device experience.
Does Soniox require an internet connection?
Yes. Real-time Soniox Speech-to-Text uses a cloud WebSocket API and therefore requires network connectivity.
Depending on your device architecture, the connection can be managed by the wearable itself or by a connected phone or companion application.
How quickly does Soniox return live transcription?
Soniox streams non-final transcription tokens while speech is still arriving instead of waiting for a complete utterance or recording.
End-to-end latency in a wearable product also depends on factors such as microphone capture, network connectivity, application processing, and display rendering.
Can Soniox identify different speakers around the wearer?
Yes. Speaker diarization can automatically detect speaker changes and attach speaker labels to transcript tokens.
This can be used for speaker-aware captions, conversation history, meeting capture, and ambient memory experiences.
Can Soniox automatically detect the language being spoken?
Yes. Soniox can identify spoken languages automatically and attach language information to transcript tokens.
It also supports multilingual conversations where speakers switch languages during the same stream.
Can I improve recognition of names, places, and product terminology?
Yes. Soniox context lets your application provide information such as names, places, organizations, product terminology, topics, and other domain-specific vocabulary with each transcription session.
This is useful for wearable products where the words that matter can depend heavily on the user or situation.
What audio formats can wearable applications stream?
Soniox supports common container formats as well as raw audio streams, including PCM formats commonly used for real-time microphone audio.
For raw streams, your application specifies the encoding, sample rate, and number of channels when opening the real-time session.
Does Soniox store audio from wearable devices?
Real-time API requests are processed transiently and are not stored by Soniox.
Soniox also states that customer audio, transcripts, and other customer content are not used to train its models. Different storage behavior applies when using asynchronous services that require stored content.
Can wearable data be processed in a specific geographic region?
Yes. Soniox supports regional data residency for eligible projects, allowing audio and transcript content to remain within the selected region for processing and storage.
Current documented regions include the United States, European Union, Japan, and India.
Build wearable experiences that understand speech in real time
Add fast transcription, live captions, translation, speaker awareness, and multilingual speech recognition to smart glasses, earbuds, watches, and the next generation of wearable devices.