Text-to-speech API for games, NPCs, and live interactive characters
Build NPCs, AI companions, interactive stories, and character-driven apps with Soniox Text-to-Speech API. Choose from 200+ studio-quality voices or clone your own, direct emotion, and keep each character consistent across 60+ languages.
$0.70 per generated hour.
Trusted by teams building global voice products















Voice infrastructure for dynamic game characters
Scripted dialogue only covers what you know a character will say in advance. Branching stories, AI characters, and player-driven conversations generate dialogue at runtime. Soniox Text-to-Speech API gives games one voice layer for pre-rendered lines and dynamic speech, with consistent character identity across languages.
Direct character emotion line by line
Use audio tags to control emotion, delivery, pace, volume, pitch, and vocal reactions, from whispers and laughter to panic, tension, and excitement. Write the direction into each line and generate the performance the scene needs.
Cast or clone every character voice
Choose from 200+ built-in studio-quality voices spanning different ages, accents, and styles, or clone an approved voice actor or character voice and use the same identity across every generated line.

Stream dialogue for real-time characters
Send text from your language model, dialogue system, or game logic as it becomes available and begin playback before the full response is generated, so interactive characters can answer without waiting for the complete line.
Handle player interruptions naturally
Character-level timestamps show exactly what has already been spoken, so your application can stop playback when a player interrupts and keep dialogue state aligned with what the player actually heard.
Build characters players can talk to
Pair Soniox Text-to-Speech API with Soniox Speech-to-Text API to build complete two-way voice interaction. Players speak naturally, your dialogue system receives what they said, and the character responds in its own voice.
Listen
Stream player speech through Soniox Speech-to-Text API and receive the transcript your dialogue system, language model, or game logic needs.
Respond
Pass the transcript to your dialogue model, character logic, narrative system, or game state to decide what happens and what the character says next.
Speak
Stream the response through Soniox Text-to-Speech API using the character's voice and the emotion or delivery the current scene requires.
Localize every character across 60+ languages
Every built-in and cloned Soniox voice speaks all 60+ supported languages. Ship localized games and interactive experiences while preserving the same character voice across every market.
From dialogue system to in-game speech
Build one character voice pipeline for scripted dialogue, branching narratives, and runtime AI responses. Pre-render speech as assets or generate it dynamically while the game is running.
Generate dialogue
Take scripted lines from your dialogue tools or generate new dialogue at runtime from a language model, branching narrative, player state, or game logic.
Direct
Assign a built-in or cloned voice to each character and add audio tags wherever a line needs a specific emotion, pace, pitch, volume, or reaction.
Generate speech
Pre-render scripted lines with the REST API or stream dynamic dialogue over WebSocket at runtime, with up to 5 streams on one connection.
Play and synchronize
Play generated audio in game and use character-level timestamps to synchronize subtitles, dialogue boxes, animations, and interruption handling with the spoken line.
Text-to-speech API features for games and AI characters
Build character voice systems with programmatic control over performance, voice identity, real-time generation, concurrency, localization, and timing.
Expressive audio tags
Control emotion, volume, pace, and pitch inline with tags like [whispering], [shouting], or [nervous]. Tags are written in English regardless of the dialogue language.
Voice cloning
Create a character voice from a reference clip in Soniox Console or through the API, then use its voice ID like any built-in voice across every supported language.
Explore voice cloningConcurrent character streams
Run up to 5 independent streams on one WebSocket connection, each with its own voice and language, for scenes where multiple characters need independent speech generation.
Explore streamsCharacter-level timestamps
Receive start and end times for every spoken character so your application can synchronize subtitles and interfaces and handle interruptions precisely.
Explore timestampsSpeech infrastructure for massive scale
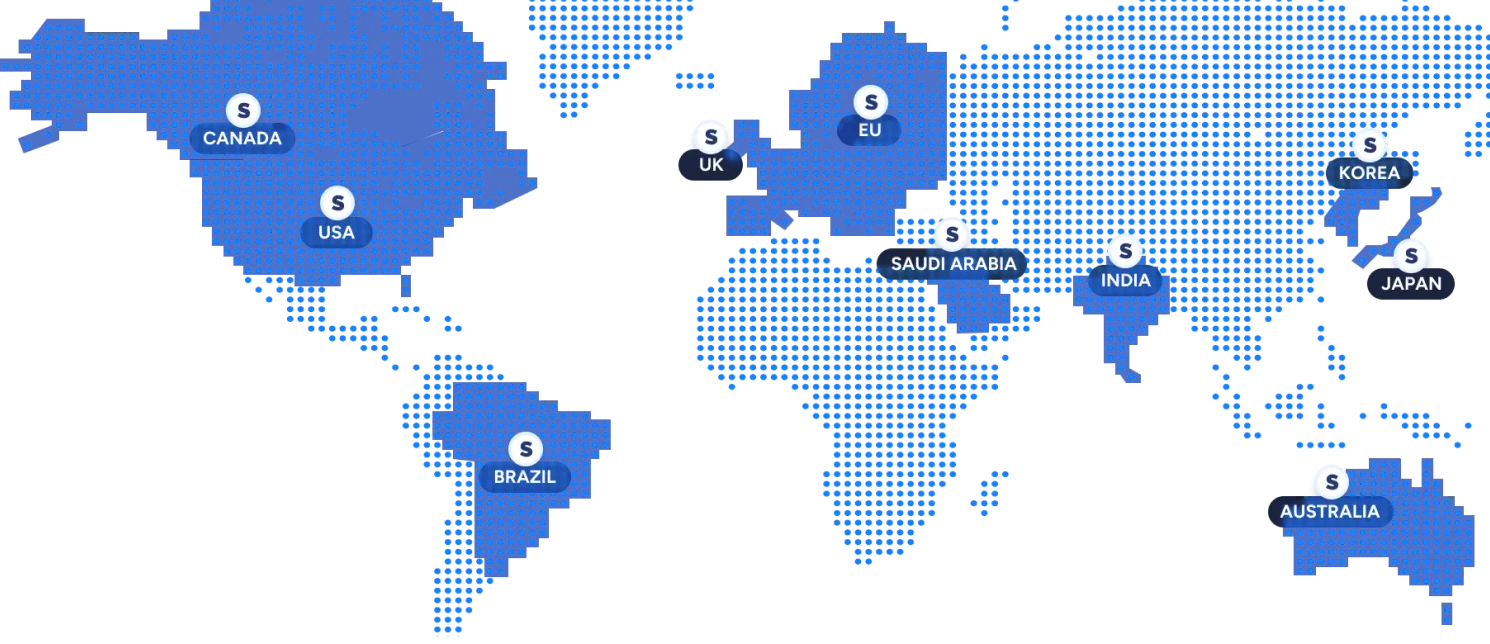
Build on one API and deploy in your region
Use the same models and API everywhere, with in-region processing to meet latency, data residency, and regulatory requirements.
Available: US, EU, Japan, India
Coming soon: Korea, Australia, Canada, Saudi Arabia, UK, Brazil
Run mission-critical systems with confidence
- 99.9% uptime
Production-hardened infrastructure with monitoring and redundancy. - low-latency streaming
Process speech in real time with low latency for responsive voice applications. - Priority support
Severity-based incident response with direct access to the Soniox team.
"Before Soniox, our international users always had a noticeably different experience. Now accuracy and responsiveness match across all regions…it feels like one system instead of five."
Alon Yair CTO of Onvego
Build voice into every interactive experience
Add generated character voice and two-way speech interaction to games, NPCs, AI companions, interactive stories, virtual worlds, and game development tools.
Games and NPCs
Add voice to NPC dialogue, quest lines, cutscenes, and in-world conversations, with scripted or dynamically generated speech from the same API.
AI companions and characters
Build LLM-driven characters that respond with a consistent voice, stream speech in real time, and express emotion as the conversation changes.
Interactive fiction
Generate voice for branching stories and narrative experiences where player choices determine dialogue at runtime.
Virtual worlds and social platforms
Add configurable voices to avatars, virtual characters, and social experiences using built-in or cloned voices across 60+ languages.
Game engines and developer tools
Embed voice generation into dialogue editors, engine plugins, modding tools, and content pipelines so developers can generate speech where they build.
Prototyping and placeholder voice
Generate temporary dialogue during development to test pacing, timing, and story flow, then regenerate instantly whenever scripts change.
Privacy and compliance, built right in
Never stored, never saved.
Audio stays in memory, everything is processed in real-time.
Built for privacy-critical use cases.
Adhering to leading global security, privacy, and compliance standards.
Trusted where privacy matters most.
Used in industries where speech is sensitive, from healthcare to enterprise.
Frequently asked questions about text-to-speech APIs for games
How can I add text-to-speech to a game or character app?
Send character dialogue to Soniox Text-to-Speech API and receive generated speech that your game or application can play directly.
Use REST to pre-render scripted dialogue or WebSocket streaming for NPCs, AI characters, branching narratives, and other runtime-generated speech.
Can I use Soniox Text-to-Speech API for NPC voices?
Yes. Assign each NPC a built-in or cloned voice and generate scripted dialogue ahead of time or dynamically at runtime.
Audio tags let your dialogue system control emotion, pacing, volume, pitch, and vocal delivery for individual lines.
Can AI characters respond in real time?
Can players talk to NPCs and AI characters with voice?
Yes. Pair Soniox Text-to-Speech API with Soniox Speech-to-Text API to build complete two-way voice interaction.
Soniox Speech-to-Text API transcribes player speech, your language model or game logic determines the response, and Soniox Text-to-Speech API streams the character's answer back in its assigned voice.
Can my game handle players interrupting AI characters?
Can several characters generate speech at once?
One WebSocket connection can run up to 5 independent streams, each with its own voice and language.
By default an account can run 3 concurrent streams across all connections. You can request a higher limit in Soniox Console.
How can my game control a character's emotion?
Add audio tags directly to the dialogue text. Tags can control emotion, volume, pace, pitch, and vocal quality, for example [whispering], [shouting], or [trembling voice].
This lets your dialogue or narrative system change how a character speaks based on scene state, player choices, or generated responses.
Can I clone a voice actor for a game character?
Can I localize the same character voice across languages?
How much does generated character speech cost?
Build voice into your characters
Add expressive character voices, real-time dialogue, voice cloning, multilingual speech, and precise timing to games and interactive products with Soniox Text-to-Speech API. Pair it with Soniox Speech-to-Text API for complete two-way voice interaction.