Text-to-speech API with emotion and tone control
Generate expressive speech you can direct line by line. Add emotion, tone, pitch, pauses, and human sounds with audio tags written directly into the text you send.
$0.70 per generated hour.
Trusted by teams building global voice products















Expressive text-to-speech you can direct
Natural speech is only the starting point. Soniox Text-to-Speech API lets your application control how each line is performed, from excitement and reassurance to whispers, hesitation, laughter, tension, and dramatic pauses.
Control emotion line by line
Place audio tags directly before the text you want to affect. Change emotion and delivery throughout the same utterance instead of choosing one fixed speaking style for the entire response.
Natural expression even without tags
Soniox already adapts rhythm, pacing, emphasis, and expression to the meaning of the text. Audio tags give your application additional control whenever a line needs a specific performance.

Natural and expressive
I thought I knew exactly how the evening would unfold. Then the phone rang. For a moment, I considered letting it go to voicemail—but something told me to answer.

Conversational
Absolutely. I found three flights that arrive before noon. The first is the least expensive, but the second gives you a much shorter connection. Would you like me to compare them?

Storytelling
By the time we reached the top of the hill, the sun was already beginning to set. We stopped for a moment, looked back at the road behind us, and realized the entire valley had turned gold.
Add emotion directly to your TTS input
Emotion and tone control lives inside the text your application already sends. Add bracketed audio tags wherever you want the delivery to change, with no separate performance timeline or editing workflow.
Control speech with audio tags
Write tags directly into the text field. The tag changes how the following words are delivered.
{
  "model": "tts-rt-v2",
  "language": "en",
  "voice": "Adrian",
  "audio_format": "wav",
  "text": "[excited] INCREDIBLE news! [calm] Let me explain what happened."
}
Shape delivery with punctuation
Formatting also influences delivery. Use uppercase for strong emphasis, *stress* for individual words, ... for hesitation, and ?! for incredulity.
You did WHAT?!
Oh, *you* noticed the haircut?
Wait... N-n-no. That can't be right.
Control emotion, tone, pace, pitch, volume, and more
Use audio tags to direct different dimensions of the performance. Tags can change throughout the utterance, giving your application line-by-line control over how speech sounds.
Emotion
Tone and manner
Human sounds
Volume
Pace, pitch, and voice quality
Pauses
Emotional text-to-speech across 60+ languages
Use the same emotion and tone controls across every supported language. Audio tags stay in English while the spoken text can be generated in any of 60+ languages.
One set of audio tags for every language
Use the same English tags regardless of the language being spoken. For example, [excited] works with Spanish text just as it does with English text.
{
  "model": "tts-rt-v2",
  "language": "es",
  "voice": "Adrian",
  "text": "[excited] ¡Tengo noticias INCREÍBLES! [calm] Déjame explicarte lo que pasó."
}
The same expressive voice in 60+ languages
Keep the same voice identity while changing languages, and use the same emotion, tone, and delivery controls throughout your multilingual product.
Give cloned voices the same expressive control
Create a high-fidelity cloned voice and direct it with the same emotion, tone, pace, pitch, volume, pauses, and human-sound tags available to built-in voices.

Expressive TTS also works in real time
Stream expressive speech while text is still arriving, so voice agents, interactive characters, tutors, and other dynamic applications can generate directed delivery at runtime.
Stream expressive speech as text arrives
Send text progressively and begin playback before the complete message is available, including responses that contain audio tags and directed delivery.
Control pacing without losing natural delivery
Adjust pauses and overall speaking rate while preserving fluent, expressive speech for the pace your product and users need.
Estimate your expressive text-to-speech cost
Set your expected generated speech volume to estimate the cost of using Soniox Text-to-Speech API for expressive and emotional speech.
Pricing calculator
Stop overpaying for speech AI
1,000 hours of speech / month
Pricing assumptions
Based on public pay-as-you-go pricing. Enterprise discounts and committed-use contracts may differ. Some providers charge separately for certain features. The calculator uses the public price for the provider configuration that most closely matches Soniox.
Speech infrastructure for massive scale
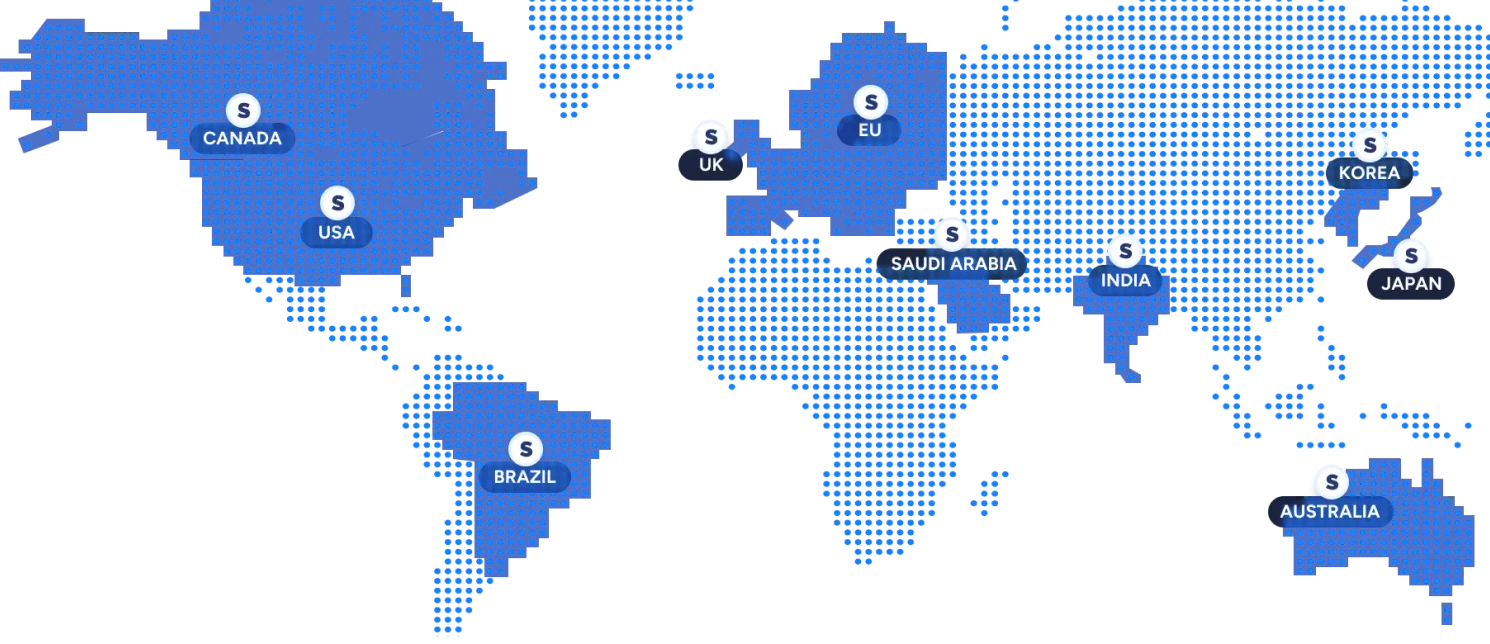
Build on one API and deploy in your region
Use the same models and API everywhere, with in-region processing to meet latency, data residency, and regulatory requirements.
Available: US, EU, Japan, India
Coming soon: Korea, Australia, Canada, Saudi Arabia, UK, Brazil
Run mission-critical systems with confidence
- 99.9% uptime
Production-hardened infrastructure with monitoring and redundancy. - low-latency streaming
Process speech in real time with low latency for responsive voice applications. - Priority support
Severity-based incident response with direct access to the Soniox team.
"Before Soniox, our international users always had a noticeably different experience. Now accuracy and responsiveness match across all regions…it feels like one system instead of five."
Alon Yair CTO of Onvego
Build products where the voice needs to perform
Add expressive text-to-speech to games, narration, video, conversational agents, learning products, and accessible voice experiences with programmatic control over how every line sounds.
Games and interactive characters
Direct NPCs, AI companions, and interactive characters with emotions, reactions, whispers, laughter, tension, and other scene-specific delivery.
Audiobooks and narration
Build expressive narration with control over dialogue, emotion, pacing, emphasis, and character delivery throughout long-form content.
Video voiceover
Generate voiceovers with directed energy, emphasis, pacing, emotion, and vocal style for explainers, ads, courses, and localized video.
Voice agents
Give conversational agents warmer, calmer, more reassuring, or more energetic delivery based on the context of each response.
E-learning and training
Make lessons, tutors, and role-play scenarios more engaging with controlled emphasis, emotion, pace, and character delivery.
Accessible voice experiences
Generate natural speech with pacing, emphasis, and tone that make spoken interfaces and long listening sessions easier to follow.
Privacy and compliance, built right in
Never stored, never saved.
Audio stays in memory, everything is processed in real-time.
Built for privacy-critical use cases.
Adhering to leading global security, privacy, and compliance standards.
Trusted where privacy matters most.
Used in industries where speech is sensitive, from healthcare to enterprise.
Frequently asked questions about emotional and expressive text-to-speech
Can text-to-speech generate speech with emotion?
[happy], [sad], [angry], [excited], [nervous], and [calm] directly inside the input text.How do I control emotion in Soniox Text-to-Speech?
[excited], [whispering], or [laughs] directly into the text you send. Place the tag before the words you want to affect, and those words inherit that delivery.Can I control tone as well as emotion?
[warm], [stern], [serious], [playful], [sarcastic], and [reassuringly], in addition to emotional states.Can I control pace, pitch, volume, and voice quality?
[slowly], [quickly], [whispering], [shouting], [low voice], [breathy], and [trembling voice].Can text-to-speech generate laughter, sighs, and other human sounds?
[laughs], [chuckles], [sighs], [gasps], [sobs], and [yawns].Can I shape delivery without using audio tags?
UPPERCASE for stronger emphasis, *stress* to stress a word, elongated spellings, and punctuation such as ... or ?!. These techniques can also be combined with audio tags.Do emotion and tone controls work in other languages?
Can cloned voices use emotion and tone control?
How many audio tags can I combine?
[warm] [softly], normally combine well. Keep each tag short and single-purpose. Large stacks of conflicting directions are less reliable.What happens if Soniox does not recognize an audio tag?
Can expressive TTS be generated in real time?
How do I change the overall speaking rate?
How much does Soniox Text-to-Speech cost?
How do I start building expressive text-to-speech?
Add audio tags directly to the text you send to Soniox Text-to-Speech API wherever you want the delivery to change.
Read the emotion and tone documentation for supported tags, examples, and implementation details.
Make every line sound the way you want
Build expressive text-to-speech with programmatic control over emotion, tone, pace, pitch, volume, pauses, and human sounds. Direct every line with Soniox Text-to-Speech API across 60+ languages.
Ready to get started?
Create an account instantly, or contact us to design a custom package for your business.
Build with APIDocumentation
Get up and running in minutes and spend your time building, not wrestling with the API.
Explore docsSee what you’ll pay
Pay only for what you use with our flexible pricing. Built to scale with you.
Pricing details