Semantic endpoint detection
for real-time speech
Know when a speaker has finished an utterance. Soniox evaluates speech and conversational context, then finalizes the segment and emits an end token.
$0.12/hour real-time · endpoint detection included
Start the demo and pause in the middle of a thought. Soniox waits for a completed utterance before marking the endpoint.
Trusted by teams building global voice products















Detect completed utterances, not just silence
Voice activity detection tells you when speech stops. Semantic endpointing also evaluates the transcript and conversational context to decide whether an utterance is complete.
“Soniox knows who’s speaking and when each thought ends. The real-time transcripts read like true dialogue, not data dumps.”
Adam Strom, Co-Founder & President at Mobius MDSemantic endpointing
Use pauses, intonation, speech patterns, and context to distinguish a finished utterance from a brief hesitation.
Tunable behavior
Adjust the latency profile, endpoint sensitivity, and maximum endpoint delay for your application.
A clear end signal
Receive one final <end> token after the segment so your application knows when to act.
Control endpoint latency and sensitivity
Choose an overall latency profile, adjust how likely the model is to emit an endpoint, and set an upper bound for the delay after speech ends.
endpoint_latency_adjustment_levelLatency adjustment
Choose how aggressively Soniox reduces endpoint latency. Higher levels return endpoints sooner and can split speech into more segments.
endpoint_sensitivityEndpoint sensitivity
Increase sensitivity to make endpoints more likely. Reduce it when speakers pause often or need more time to finish a thought.
max_endpoint_delay_msMaximum endpoint delay
Set a hard upper bound on how long Soniox can wait to return an endpoint after speech has ended.
Enable endpoint detection in one request
Enable endpoint detection in the real-time request. Soniox finalizes the segment and returns an end token when the utterance is complete.
Request
{
  "enable_endpoint_detection": true
}
Final tokens
{"text": "What's",    "is_final": true}
{"text": " the",      "is_final": true}
{"text": " weather",  "is_final": true}
{"text": " in",       "is_final": true}
{"text": " San",      "is_final": true}
{"text": " Francisco","is_final": true}
{"text": "?",         "is_final": true}
{"text": "<end>",     "is_final": true}
Endpoint detection in Python
from soniox import SonioxClient
from soniox.types import RealtimeSTTConfig
from soniox.utils import start_audio_thread, throttle_audio

client = SonioxClient()
config = RealtimeSTTConfig(
    model="stt-rt-v5",
    audio_format="mp3",
    enable_endpoint_detection=True,
)

audio = throttle_audio("conversation.mp3", delay_seconds=0.1)

with client.realtime.stt.connect(config=config) as session:
    start_audio_thread(session, audio)

    for event in session.receive_events():
        for token in event.tokens:
            if token.text == "<end>":
                print("\nEndpoint detected")
            elif token.is_final:
print(token.text, end="", flush=True)Compare real-time endpoint detection
Compare endpoint detection, manual finalization, latency controls, and timestamps across each provider’s real-time model.
| Feature | Soniox stt-rt-v5 | OpenAI gpt-4o-transcribe | Google gemini-3.5-transcribe-live | Azure en-US-Conversation | Speechmatics enhanced | Deepgram nova-3 | AssemblyAI Universal-3.5 Pro | Cartesia ink-2 | ElevenLabs Scribe v2 Realtime | Meta muse-voice-transcribe-1.0 | Smallest AI Pulse | xAI grok-voice-transcribe-2.0 | Inworld inworld-stt-1 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Endpoint detection | |||||||||||||
| Manual finalization | |||||||||||||
| Real-time latency config | |||||||||||||
| Timestamps |
More than a silence timeout
Soniox combines acoustic and conversational signals instead of finalizing every time a fixed period of silence passes.
Three endpoint controls
Tune latency, sensitivity, and maximum delay directly in the real-time API request.
Final text and end token
One stream provides provisional text, final transcript tokens, and the endpoint signal for downstream logic.
Built for real-time speech applications
Use endpoint events whenever your application needs to act on a completed utterance.
Voice agents
Use the end token to submit a completed user utterance to an LLM and begin the next response.
Call centers and IVR
Detect completed caller requests in live conversations without relying on one fixed silence timer.
Hands-free devices
Mark complete voice commands and user turns in wearable and embedded conversational interfaces.
Speech infrastructure for massive scale
Build on one API and deploy in your region
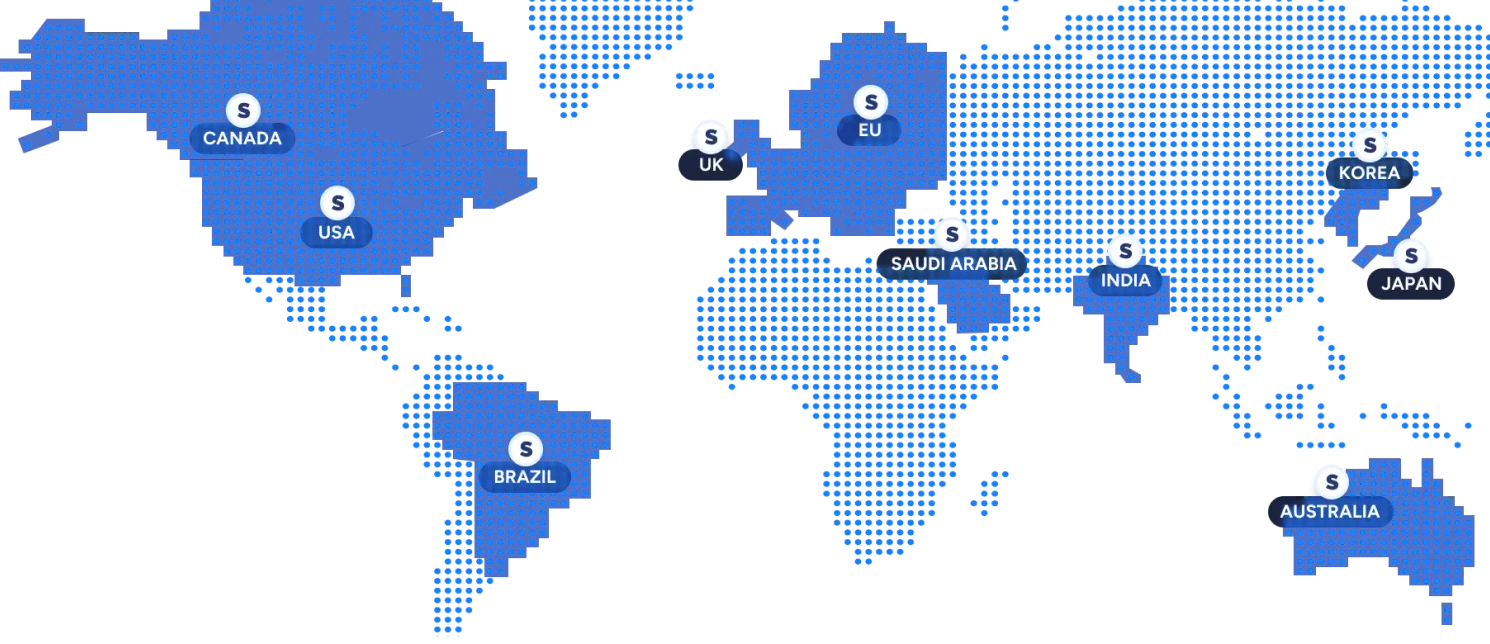
Use the same models and API everywhere, with in-region processing to meet latency, data residency, and regulatory requirements.
Available: US, EU, Japan, India
Coming soon: Korea, Australia, Canada, Saudi Arabia, UK, Brazil
Run mission-critical systems with confidence
- 99.9% uptime
Production-hardened infrastructure with monitoring and redundancy. - low-latency streaming
Process speech in real time with low latency for responsive voice applications. - Priority support
Severity-based incident response with direct access to the Soniox team.
"Before Soniox, our international users always had a noticeably different experience. Now accuracy and responsiveness match across all regions…it feels like one system instead of five."
Alon Yair CTO of Onvego
Endpoint detection included in real-time STT
Set your monthly real-time audio volume to estimate your Soniox API cost. Endpoint detection is included in the hourly transcription rate.
Pricing calculator
Stop overpaying for speech AI
1,000 hours of audio / month
Pricing assumptions
Based on public pay-as-you-go pricing. Enterprise discounts and committed-use contracts may differ. Some providers charge separately for certain features. The calculator uses the public price for the provider configuration that most closely matches Soniox.
Privacy and compliance, built right in
Never stored, never saved.
Audio stays in memory, everything is processed in real-time.
Built for privacy-critical use cases.
Adhering to leading global security, privacy, and compliance standards.
Trusted where privacy matters most.
Used in industries where speech is sensitive, from healthcare to enterprise.
Frequently asked questions about endpoint and turn detection
What is endpoint detection?
Is voice activity detection the same as endpoint detection?
Is endpoint detection the same as turn detection?
How does semantic endpointing work?
How do I enable endpoint detection?
enable_endpoint_detection to true in the real-time request. The default latency level is 0, sensitivity is 0.0, and maximum endpoint delay is 2000 ms.What does the end token mean?
<end> token. Use it to trigger an LLM, execute a command, submit a turn, or store stable text.How can I make endpoint detection faster?
endpoint_latency_adjustment_level or endpoint_sensitivity. You can also lower max_endpoint_delay_ms for a stricter upper bound. More aggressive settings can create more segments and slightly reduce recognition accuracy.How can I prevent endpoints from firing too early?
Does endpoint detection affect speaker diarization?
What is the difference between endpoint detection and manual finalization?
Can Soniox replace Silero VAD or WebRTC VAD?
How do I get started?
Ready to get started?
Create an account instantly, or contact us to design a custom package for your business.
Build with APIDocumentation
Get up and running in minutes and spend your time building, not wrestling with the API.
Explore docsSee what you’ll pay
Pay only for what you use with our flexible pricing. Built to scale with you.
Pricing details